
Key takeaways
- PerplexityBot supports search discovery. Perplexity-User fetches pages for user actions. Perplexity says neither identity collects content for training AI foundation models. [1]
- A PerplexityBot robots.txt restriction addresses automatic discovery. Perplexity says its user-requested fetcher generally ignores robots.txt. [1]
- Each identity has a separate official address feed. Match the declared name with the corresponding current ranges before granting a network exception. [1]
- A crawl, a successful response, an answer citation, and a human visit are different observations. Investigate them separately.
PerplexityBot discovers content for search; Perplexity-User retrieves pages in response to user actions. For website owners, this difference determines which access controls to review and what a recorded request can tell you. The two identities have separate purposes and separate published network ranges. [1]
Start with your goal: do you want public pages discoverable in Perplexity search, do you want to investigate a requested visit, or do you need to restrict actual website access? A robots preference can answer the first question without fully answering the other two.
This guide explains the basic distinction first, then covers identification, robots.txt examples, request verification, firewall considerations, and troubleshooting. The technical references were reviewed on 17 November 2026. Check the linked operator and infrastructure documentation before changing website-wide rules.
PerplexityBot and Perplexity-User at a glance
| Identity | Documented role | Robots.txt treatment | What a request does not prove |
|---|---|---|---|
| PerplexityBot | Finds pages to surface and link in Perplexity search results | Operator documents a bot-specific search-crawl preference | That the page was selected for an answer or visited by a person |
| Perplexity-User | Retrieves pages to help answer user requests | Operator says the user-requested fetcher generally ignores robots.txt | That a person opened your website or that the page was used for training |
Perplexity's current crawler reference documents these two names. Both are request identities rather than policy-only tokens, and both are recognized by Ansvra's current analyzer registry. Recognizing a declared name is separate from authenticating the sender. [1]
Search discovery versus a requested visit
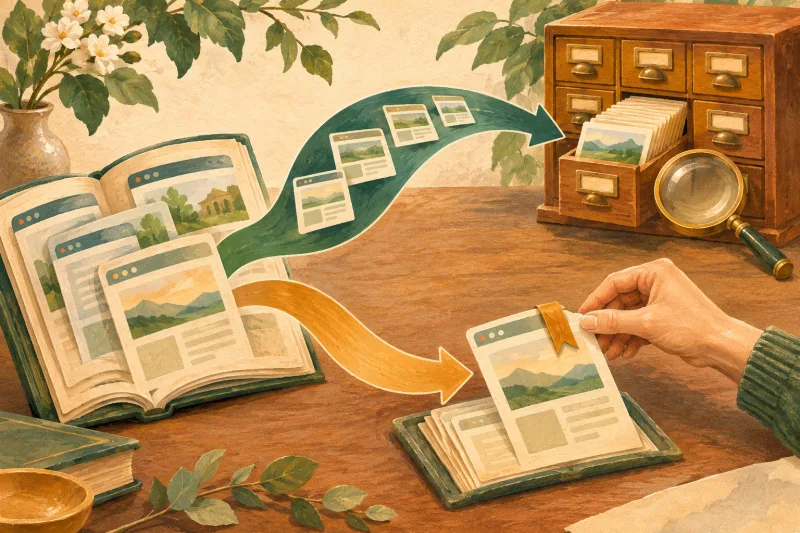
A useful analogy is a library catalog and a requested book. Cataloging helps people discover material later. Fetching a book responds to a particular need. Both activities involve the same collection, but they do not have the same trigger or necessarily produce the same visible evidence.
A website crawl records an automated request for a resource. Search discovery concerns finding material that may support later results. A user-directed fetch obtains material for a task. A citation is an actual source reference in an answer. A referral is a separate website visit associated with an identifiable referring source. Do not turn those steps into a measured customer journey just because they concern the same URL.
Select a branch to inspect the documented purpose and control limitation.
- Your public website
The same page can be requested for different purposes. [1]
Next: PerplexityBot, Perplexity-User
- PerplexityBot
Automatic search discovery. Configure the named crawl preference and check the corresponding current IP feed. [1]
- Perplexity-User
User-requested retrieval. Perplexity says this fetcher generally ignores robots.txt; use its separate IP feed for network checks. [1]
Conceptual purpose map, not internal architecture or measured request data. A request does not establish a citation or a human visit. Perplexity states that neither identity collects content for foundation-model training. [1]
The two paths describe documented purposes, not Perplexity's internal architecture or a reconstruction of observed traffic. A source link does not establish exactly when a page was fetched, which identity supplied it, or whether the website received a fresh request for that particular answer. Inspect the evidence for the question you are trying to answer.
PerplexityBot: automatic search discovery
PerplexityBot is designed to discover websites for Perplexity search results. The operator recommends permitting its robots.txt access and its published network ranges when search discovery is the website owner's intention. Permission creates access conditions; it does not guarantee that a specific page will be selected, linked, or cited. [1]
The exact token is PerplexityBot. The operator's current example is:
Mozilla/5.0 (compatible; PerplexityBot/1.0; +https://perplexity.ai/perplexitybot)The version is an example and may change. Identify the documented token without requiring that every future request reproduce the complete string above. A link inside a user-agent header is not independent verification, since a requester can copy it. [1]
Perplexity publishes the associated ranges at perplexitybot.json. Use the current feed, not a permanently copied address from an article. Keep the declared identity and the network evidence together when investigating access. [2]
The operator says this bot does not crawl content for AI foundation models. Keep that statement scoped to the documented crawler and purpose. It is not evidence that no organization could ever obtain or use the same publicly available material through another route. Conversely, seeing PerplexityBot is not evidence that your page trained a specific model. [1]
Perplexity-User: a page fetch prompted by a user
Perplexity-User supports actions requested within Perplexity. A question may cause the service to visit a page to help produce an answer and potentially link to that page. The operator distinguishes this from automatic crawling and foundation-model training collection. [1]
The exact token is Perplexity-User. Its documented example is:
Mozilla/5.0 (compatible; Perplexity-User/1.0; +https://perplexity.ai/perplexity-user)It has its own published feed, perplexity-user.json. A rule for PerplexityBot's ranges is not a complete configuration for this identity. Maintain each set according to its own official source. [1] [3]
The access caveat is especially important: the current reference says that, because the fetch is requested by a user, this fetcher generally ignores robots.txt. Do not promise that a Perplexity-User Disallow group will prevent these visits. A preference file is not the same as enforcing an access decision at the website. [1]
Perplexity's reference introduces the two settings as independent, while giving the user fetcher this explicit exception. Read the introduction together with that detailed behavior. It would be misleading to simplify the page into “both bots always obey the same robots rules.”
A fetch at a user's request is still an automated website request. It does not itself establish a human session, an analytics referral, or a conversion. If the question is whether someone clicked an answer link, investigate traffic evidence separately.
Choose a website policy before changing rules
Write down what you want to happen for each activity. A public publication may welcome search discovery but still keep account pages protected. Another website may decline automatic discovery and investigate user-requested fetches separately. Give each decision an owner, and record which hostnames and paths it covers.
Allow automatic discovery on public paths
This robots.txt fragment permits PerplexityBot across the host. Review and merge it with your existing file rather than replacing unrelated rules. It expresses a crawl preference; it does not remove authentication, override a firewall, or promise a search appearance. [1]
User-agent: PerplexityBot
Allow: /
If the file already contains general exclusions, preserve the ones that should apply. Under the Robots Exclusion Protocol, a matching bot-specific group does not automatically inherit a wildcard group's restrictions. Multiple matching groups for the same token are combined. Appending an isolated root-wide allow can therefore change more than you intended. [4]
Restrict a section while allowing the rest
For a section that should not be automatically crawled by PerplexityBot, use a more specific path rule. In this example, the /members/ restriction takes precedence over the shorter root allow. If the content is private, enforce authorization as well. [4]
User-agent: PerplexityBot
Allow: /
Disallow: /members/
Test the intended restricted path and a neighboring public path. Check path case and existing exceptions. The standard uses the most specific matching path; an equivalent allow/disallow match favors allow. The order of the lines is not a general “last rule wins” mechanism. [4]
Decline PerplexityBot's automatic crawl
If your decision is to opt out of that bot's automatic crawl, this is the relevant named group. Its scope is PerplexityBot, not every possible Perplexity product, browser task, or user-requested fetch. [1]
User-agent: PerplexityBot
Disallow: /
Publish robots.txt at the relevant origin's root and check each applicable hostname. A policy on a main domain does not configure a separate publication subdomain, asset host, or redirect destination. The protocol scopes the file to its own scheme and authority. [4]
Perplexity says preference changes can take up to 24 hours to be reflected by its systems. That is not a promise of a recrawl, result removal, or new citation within that period. It also does not cancel the documented Perplexity-User exception. [1]
Restrict actual retrieval when necessary
For confidential pages, use authentication and authorization. For a deliberate network restriction, work with your website team to enforce it at the appropriate layer and confirm the outcome. Robots.txt is public crawl guidance, not a security mechanism. [4]
Do not present another platform's training token, noai-style tag, or llms.txt file as a universal Perplexity blocking control. The reviewed bot reference does not establish those promises. Keep supported preferences and enforced access rules distinct, and avoid claiming that a new restriction deletes previously obtained content.
Verify a Perplexity request
A User-Agent header is supplied by the requester and can be imitated. Perplexity recommends combining the bot name with the corresponding published address ranges. Its two feeds are separate sources of truth for those range checks. A match supports attribution to the documented traffic, not a conclusion about later model use or answer placement. [1]
- Capture the exact observation. Keep the timestamp, hostname, requested path, method if available, response status, and declared identity together. Start with the failed request you actually need to explain.
- Establish the network source. Behind a reverse proxy, the origin may see a proxy address. Use your infrastructure's trusted client-address handling rather than treating any submitted forwarded header as authoritative.
- Choose the matching official feed. Compare PerplexityBot against perplexitybot.json and Perplexity-User against perplexity-user.json. Do not treat all addresses in a shared hosting provider as operator-owned.
- Review the protection outcome. Confirm whether an edge rule, origin rule, rate limit, challenge, or authentication decision handled the request. A range match does not make every website resource public.
Give any operational range-update process an owner. Refresh from the maintained feeds, validate the downloaded structure before applying it, and retain a known-good configuration if an update cannot be checked. This is an operational recommendation, not a claim that a feed's timestamps guarantee a particular refresh schedule. [2] [3]
The reviewed reference does not supply a universal reverse-DNS verification suffix or a signed-request mechanism for these two identities. Do not invent one. If you have only a matching declared name, describe the request as identified rather than operator-verified.
Firewall access: pair each name with its own ranges
A Web Application Firewall, or WAF, can block a request even when robots.txt permits it. Perplexity's guidance recommends checking both the declared bot and its own range set. Preserve that pairing in the rule logic: one branch for PerplexityBot, and another for Perplexity-User. [1]
The following is explanatory logic, not a ready-to-deploy expression. Replace it with your provider's supported syntax and current maintained lists:
(PerplexityBot identity AND current PerplexityBot ranges)
OR
(Perplexity-User identity AND current Perplexity-User ranges)
A loose rule that permits either name from either address set loses the per-identity pairing. A rule that trusts only the name is weaker still. Keep any exception scoped to the necessary public website access; there is no need to grant access to account or administrative resources.
Cloudflare: understand what Skip bypasses
Perplexity's Cloudflare instructions use a custom rule with paired identity/range conditions and a Skip action, positioned before relevant blocking or challenge rules. Cloudflare documents that Skip affects selected security features. Choose the features required for the justified exception rather than treating “allow this bot” as a reason to bypass every protection. [1] [5]
Rule order matters: a later exception cannot undo a block that already terminated processing. Perplexity also notes that Cloudflare Bot Fight Mode cannot be skipped with a WAF custom rule. If requests remain challenged, inspect which protection actually produced the event instead of repeatedly widening the same rule. Confirm current account capabilities and provider guidance before implementation. [1]
AWS WAF: understand priority and terminating actions
Perplexity recommends separate IP sets and rules combining each set with its matching User-Agent condition. Its documented setup uses Allow and positions the rules before blocking rules. AWS evaluates lower numeric priorities first and continues until evaluation terminates or rules are exhausted. Review the consequences of an early Allow in your own rule set. [1] [6]
After any change, compare actual permitted and denied requests. Keep a record of the intended resource scope and the previous configuration so an unintended exception can be reversed. A provider rule successfully saving is setup evidence; successful subsequent access needs its own observation.
Troubleshoot the exact request
| Symptom | Evidence to inspect | Next action |
|---|---|---|
| No recorded activity | Website, dates, source delivery, and observation coverage | Confirm that the relevant requests could have been observed before assuming a block. |
| 403 despite robots permission | Edge and origin events for the exact URL | Find the denying layer and check the paired identity/range condition. |
| 429 responses | Request timing and the rate rule responsible | Review intended limits without inventing a crawl frequency or crawl-delay guarantee. |
| 200 but unusable content | Returned body, redirects, login state, and required assets | Confirm the intended content was served rather than a challenge or empty shell. |
| User fetch after a robots restriction | Which identity requested the page | Account for Perplexity-User's documented exception; decide whether enforced access must change. |
| Firewall exception seems ineffective | Current ranges, rule ordering, and the protection producing the event | Correct the responsible layer instead of broadening unrelated exceptions. |
A manual request that copies a bot's header can test how your server responds to that declaration. It does not recreate the operator's network source, verification status, rendering behavior, or task. Record it as a response test, then inspect genuine subsequent requests separately.
The reviewed crawler reference does not establish a universal JavaScript rendering capability, cache lifetime, revisit frequency, or Crawl-delay support for these identities. Avoid filling those gaps with assumptions borrowed from Googlebot, ClaudeBot, or another crawler.
Access does not guarantee a citation or a visit
If the goal is to understand visibility, start with the actual answer and its linked URLs. A page can receive requests without appearing in the answers you observed. A visible citation can receive no identifiable referral in the period you inspected. Neither pattern is inherently evidence of broken collection or access.
Keep the website, dates, questions, platform, and usable observation coverage consistent when comparing results. Do not divide unrelated request and analytics totals and describe the result as the probability that an individual crawl produced a customer. Request counts, sessions, citations, and conversions use different units.
For a broader answer-review workflow, see how to compare sources across Google AI Mode, ChatGPT Search, and Perplexity. That investigation answers a different question from whether a particular bot could retrieve a page.
Review recorded Perplexity activity in Ansvra
When AI Agent Analyzer is available for your account and has request records for the website, review PerplexityBot and Perplexity-User separately. Both declared identities are currently recognized. Inspect relevant pages, recorded response outcomes, and dates before drawing conclusions from totals.
Check observation coverage as well as connection status. Uploaded history represents saved activity rather than continuing delivery. An empty report does not establish that no Perplexity-related request ever occurred, and matching a user-agent identity does not independently verify the requesting operator.
Use the AI Agent Analyzer guide for current setup and access instructions. Use Traffic from AI for recorded human visits and saved answer evidence for citations. These observations can support the same investigation while remaining separate measures.
Frequently asked questions
Are PerplexityBot and Perplexity-User training crawlers?
Perplexity says PerplexityBot is for search and is not used to crawl content for AI foundation models. It says Perplexity-User serves user actions and does not collect content for foundation-model training. Keep these statements scoped to the documented identities and purposes. [1]
Does blocking PerplexityBot stop every Perplexity visit?
No. The rule addresses that automatic discovery identity. Perplexity documents user-requested fetching separately and says it generally ignores robots.txt. Use appropriate enforced access controls for resources that must remain restricted. [1]
Can I reliably block Perplexity-User through robots.txt?
The current reference does not support that promise: it gives the user-requested fetcher an explicit exception. A preference file should not be presented as a guaranteed retrieval block. Authentication and network enforcement are different mechanisms. [1] [4]
Do both identities use the same published IP list?
No. Perplexity publishes separate feeds and recommends pairing each declared name with its own current ranges. Check the appropriate feed rather than merging the identities into an undifferentiated allowlist. [1]
Why does an allowed crawler still receive a challenge?
Robots permission does not override a firewall or challenge. Rule order and protection type matter. For example, the operator notes that Cloudflare Bot Fight Mode cannot be skipped by a custom WAF rule. Investigate the actual security event. [1]
How quickly do preference changes take effect?
Perplexity says its systems may take up to 24 hours to reflect changes. This does not guarantee a result appearance or removal deadline, and it does not turn the documented user-fetch exception into robots enforcement. [1]
Can Ansvra tell me which model used a crawled page?
A bot identity in request records does not establish a model version or downstream use. Review saved answer evidence for observed citations, and keep that evidence separate from request activity.
Do these two names identify every product or browser activity?
The current crawler reference documents two identities. It does not establish that every possible browser task, integration, or product declares one of them. Do not infer a complete network inventory from this list or invent additional bot tokens.
Summary
Choose your policy for search discovery and user-requested retrieval separately. Configure PerplexityBot's crawl preference, account for Perplexity-User's documented robots exception, and verify the matching identity and network evidence before changing firewall rules. Then use actual answers and website traffic to investigate citations and human visits.
Sources
- Perplexity: crawler purposes, robots behavior and firewall configurationAccessed
- Perplexity: PerplexityBot published address rangesAccessed
- Perplexity: Perplexity-User published address rangesAccessed
- IETF: RFC 9309, Robots Exclusion ProtocolAccessed
- Cloudflare: configure a custom rule with the Skip actionAccessed
- AWS: WAF rule priority and evaluation orderAccessed
Discussion
Join the discussion