
Key takeaways
- OpenAI documents four distinct identities: OAI-SearchBot for search, GPTBot for potential training collection, ChatGPT-User for certain user actions, and OAI-AdsBot for submitted advertising pages. [1]
- You can permit search crawling while declining GPTBot collection. These preferences operate independently. [1]
- A declared user agent is a clue, not proof of who sent a request. Check the relevant published address ranges; signed Cloud browser requests have a separate verification process. [1] [4]
- Robots rules, successful website access, answer citations, and human visits answer different questions. Investigate each with its own evidence.
OpenAI uses different web agents for different jobs. OAI-SearchBot helps discover pages for ChatGPT search. GPTBot collects content that may contribute to foundation-model training. ChatGPT-User retrieves pages for certain user-requested actions. OAI-AdsBot checks pages submitted as advertising landing pages. Their names are useful because the website decisions associated with them are different. [1]
For a website owner, the practical question is which activity you want to permit and whether your website actually permits it. A publisher might welcome search discovery while restricting training collection. An advertiser may need a submitted landing page to be accessible for review. A developer investigating a failed user-requested visit needs to understand more than the site's search policy.
This guide starts with those decisions, then explains identification, robots.txt examples, verification, and troubleshooting. Technical references were reviewed on 16 November 2026. Check the linked operator documentation before making infrastructure changes.
OpenAI bots at a glance
| Identity | Documented job | Main website decision | Important limit |
|---|---|---|---|
| OAI-SearchBot | Discovery for ChatGPT search | Whether to allow its automatic search crawl | Allowing access does not guarantee selection in an answer. |
| GPTBot | Collection that may be used for foundation-model training | Whether to allow this training-related collection | A request does not prove a page was used in a particular model. |
| ChatGPT-User | Certain user-initiated ChatGPT and Custom GPT actions | Whether the requested content is accessible | OpenAI says robots.txt may not apply to user-initiated actions. |
| OAI-AdsBot | Safety validation and relevance assessment of submitted ad pages | Whether the submitted landing page can be checked | OpenAI says it visits submitted ad pages and does not use its collected data for foundation-model training. |
The roles and limitations above follow OpenAI's crawler reference. All four are request identities, rather than policy-only tokens such as Google-Extended. Ansvra's current analyzer registry recognizes all four declared identities. [1]
How a website request relates to an AI answer
A crawl is an automated request for a resource. Search discovery concerns finding content that could support a later search result. Retrieval means obtaining content for a task. Training changes a model through a separate development process. An answer citing your page is another observation, and a person following that link is another event again.
These distinctions stop a common reporting mistake: treating a crawler request as a completed journey from discovery to citation to customer. A successful request establishes that a response was served. To know whether a particular answer linked to your page, inspect the answer. To know whether someone visited, inspect the available website-traffic evidence.
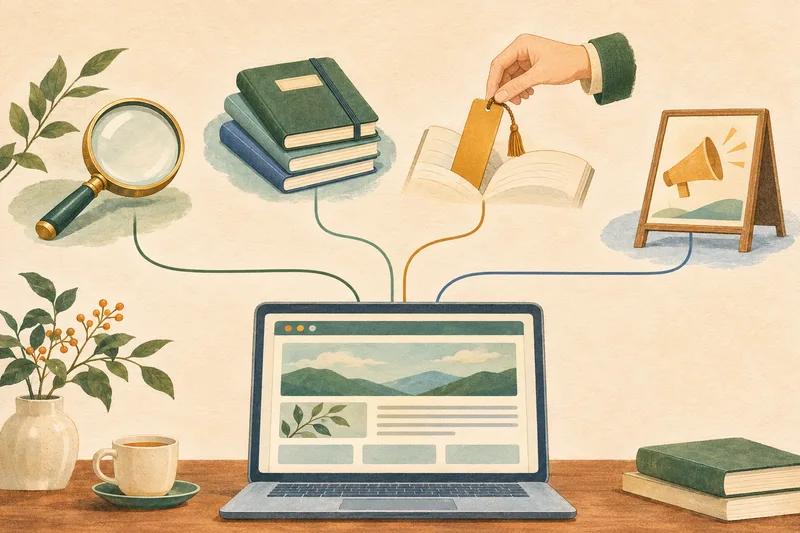
Explore each documented purpose. The branches represent uses, not four required separate network requests.
- Your website
The same public website can receive requests associated with different documented purposes. [1]
Next: OAI-SearchBot, GPTBot, ChatGPT-User, OAI-AdsBot
- OAI-SearchBot
Discovers content for ChatGPT search; access does not guarantee an answer citation. [1]
- GPTBot
Collects content that may be used for foundation-model training; independent preference from search. [1]
- ChatGPT-User
Visits for certain user actions; robots.txt may not apply. [1]
- OAI-AdsBot
Checks submitted advertising pages for safety and possible relevance; not foundation-model training. [1]
Conceptual purpose map, not internal architecture or observed request data. OpenAI may reuse a crawl for search and training when both are permitted. Signed Cloud browser traffic has separate verification. [1] [4]
The diagram describes documented purposes, not a reconstruction of OpenAI's internal systems. OpenAI says that when a website allows both OAI-SearchBot and GPTBot, it may reuse one crawl's results for both purposes to avoid duplicate crawling. Separate preferences therefore do not require two visible requests. [1]
OAI-SearchBot: discovery for ChatGPT search
OAI-SearchBot is the identity to investigate when your question concerns automatic crawling for ChatGPT search. OpenAI says sites opting out will not appear in ChatGPT search answers, although they may still appear as navigational links. A restriction is therefore more precise than a promise that your domain will never be linked anywhere. [1]
The robots.txt token is OAI-SearchBot. OpenAI publishes its current address ranges at searchbot.json. Its reference includes a browser-like user-agent example containing OAI-SearchBot/1.4; the version can change. Match the documented identity without making one example's browser version a permanent requirement. [1]
OpenAI also documents an optional robots.txt marker in the user-agent string when fetching that file. It helps distinguish a policy lookup from another resource request, especially in incomplete logs. It is not another crawler identity. Where paths are available, inspect the actual requested path as well. [1]
If search discovery is your goal, review this bot's rules and network access together. OpenAI recommends permitting its published ranges alongside robots access. After a robots.txt update, its search systems can take approximately 24 hours to adjust. That is a documented adjustment period, not a guarantee of a new crawl, indexing, or citation within a day. [1]
GPTBot: collection that may support training
GPTBot's documented role is collecting content that may be used to train OpenAI's generative AI foundation models. The word “may” matters: seeing the bot request a page does not identify the eventual dataset, model version, or processing decision. [1]
Its robots.txt token is GPTBot, and its published address feed is gptbot.json. The reference's example contains GPTBot/1.4. As with search crawling, a version or an additional robots marker should not be mistaken for a new purpose. [1]
OpenAI describes disallowing GPTBot as indicating that a site's content should not be used for foundation-model training. This setting is independent of OAI-SearchBot. A site owner can express a training restriction while retaining search discovery. [1]
A current access decision should not be reported as proof of deletion from earlier datasets or removal from an already trained model. The crawler reference does not provide that assurance. Keep your documented policy, the date it changed, and any later request evidence separate from claims about historical content use.
ChatGPT-User: retrieval prompted by a user
ChatGPT-User is used for certain actions requested through ChatGPT and Custom GPTs. A user can ask for help that results in a page visit. OpenAI explicitly distinguishes this activity from automatic web crawling and says robots.txt rules may not apply because the action is user-initiated. [1]
The identity appears as ChatGPT-User, with a documented example containing ChatGPT-User/1.0. OpenAI publishes chatgpt-user.json for its address ranges. A request declaring the name still needs corroboration before you grant it special network treatment. [1]
Blocking ChatGPT-User in robots.txt is not the documented way to opt out of ChatGPT search. OpenAI directs website owners to OAI-SearchBot for that decision. Equally, changing a search preference is not a substitute for authentication when a page is intended to remain private. [1] [2]
Do not assume every ChatGPT browsing session will declare this identity. OpenAI separately documents signed Cloud browser traffic, discussed below. A product-level name in an answer or browser interface does not establish which request identity reached your site. [4]
OAI-AdsBot: submitted advertising landing pages
OAI-AdsBot checks the safety of web pages submitted as ads on ChatGPT. OpenAI says landing-page content may also help assess when an ad is relevant. The crawler reference limits its visits to submitted ad pages and says the collected data is not used to train generative AI foundation models. [1]
The token is OAI-AdsBot, with the documented example OAI-AdsBot/1.0. Its current address feed is adsbot.json. These details distinguish advertising validation from an ordinary search crawl or training-related request. [1]
For advertisers, OpenAI says OAI-AdsBot access is required for landing-page validation and recommends also allowing OAI-SearchBot. Its checklist covers the full submitted URL, redirects, required assets, and protection layers. A homepage loading in your browser does not show that the actual ad destination works for the bot. [3]
Have your website team inspect the complete redirect chain, including any tracking destination or separate asset host. Check that the final response contains the advertised product or service rather than a challenge, login, location error, or unrelated destination. Successful access supports the check; it is not a promise of ad approval. [3]
Choose the access policy that matches your goal
Start with a written decision for each purpose. For example: permit public search discovery; decline GPTBot collection; retain authentication on private content; permit advertising checks only where the advertising workflow needs them. The resulting configuration should reflect those decisions without weakening unrelated protections.
Allow search discovery while restricting GPTBot
This robots.txt fragment permits OAI-SearchBot at the site root while disallowing GPTBot. It implements the independent controls described by OpenAI. Merge it with your existing rules after reviewing them; it is not a complete replacement file. [1]
User-agent: OAI-SearchBot
Allow: /

User-agent: GPTBot
Disallow: /
The example does not authenticate visitors, remove existing content, or change a separate firewall policy. It also does not establish controls for ChatGPT-User or signed browser sessions. Treat those as different access questions.
Restrict a section while retaining public search access
Under the Robots Exclusion Protocol, the more specific matching path rule applies. This example disallows OAI-SearchBot on paths beginning /members/ while permitting the rest. An equally specific allow/disallow conflict favors the allow rule. Review every matching group before testing your intended paths. [2]
User-agent: OAI-SearchBot
Allow: /
Disallow: /members/
A specific bot group does not automatically inherit the wildcard group's restrictions. If your general rules exclude other paths, include the appropriate restrictions in this bot's group too. Rules from multiple groups matching the same token are combined under the standard. This is why appending an isolated “allow everything” fragment can have unintended effects. [2]
Permit advertising checks where appropriate
If your policy permits OAI-AdsBot across the host, the group below expresses that preference. Check existing restrictions and required assets before applying it. Advertisers should follow OpenAI's current landing-page checklist rather than assume robots permission alone completes the setup. [3]
User-agent: OAI-AdsBot
Allow: /
Publish robots.txt at the root of the relevant origin. A rule on your main website does not configure another subdomain or a separate image host. The standard scopes the file to the scheme and authority serving it. Preserve real login and authorization controls for private resources: robots.txt is public and is not an access-security mechanism. [2]
Technical verification: identify the requester before granting access
A User-Agent header is a declaration that a requester can copy. A convincing bot name, an OpenAI documentation link inside the header, or a successful response does not independently verify ownership. Use the current official feed corresponding to the declared identity as corroborating evidence, and follow your protection provider's supported verification process. [1]
- Keep the evidence scoped. Record the time, hostname, path, response status, and declared identity for the request you are investigating. Use authorized infrastructure logs for any source-address investigation.
- Determine the real network source. At a proxied origin, a raw client-address field may identify your proxy. Use your trusted infrastructure's documented client-address handling, rather than accepting an arbitrary forwarded header.
- Check the correct current feed. Compare against the appropriate OpenAI published ranges, including the relevant address family. A range match supports network attribution; it does not prove later use in an answer or model.
- Keep changes narrow. Apply only the exception needed for the verified traffic and required resource. Retain protections for unrelated requests and review the result.
Do not copy today's feed into a permanent article allowlist. Link to the maintained source and give any operational synchronization process an owner. The crawler overview does not establish one universal crawl frequency, JavaScript capability, or crawl-delay behavior for all four identities; avoid building expectations around undocumented behavior. [1]
Signed Cloud browser traffic is a separate case
OpenAI's Cloud browser guidance describes HTTP Message Signatures: requests include Signature, Signature-Input, and a Signature-Agent value of "https://chatgpt.com". Verification uses the published signing keys and the signature standard. Merely seeing those headers is not successful verification. [4]
Use your provider's supported verified-agent integration or implement the documented signature verification. Preserve the necessary headers through proxies. OpenAI documents provider-specific agent labels, which can differ from user-agent tokens; do not turn a dashboard label into a guessed robots.txt rule. This signed-browser mechanism does not mean every GPTBot or search request carries such a signature. [4]
Troubleshoot access without confusing it with visibility
| Symptom | Check first | What to do next |
|---|---|---|
| No recorded requests | Website, date range, observation coverage, and source delivery | Establish that requests could have been observed before changing website policy. |
| 403 despite an allow rule | Which layer denied the exact request: edge protection, origin, login, or a challenge | Investigate the verified requester and resource; a robots rule does not override network enforcement. |
| 429 responses | Rate-limit evidence, timing, and the responsible rule | Adjust a justified limit narrowly and retest; do not invent a crawler's supported delay setting. |
| 200 but unusable content | Returned body, redirects, and required assets | Confirm the response contains the intended content rather than a challenge or empty shell. |
| A policy change seems ineffective | Correct host, matching groups, path, and current file | Correct the rule and allow the documented search adjustment period; do not promise an immediate new crawl. |
| Crawls but no citations | Actual saved answers and their linked URLs | Assess answer observations separately; successful access does not guarantee selection. |
OpenAI's advertiser guidance specifically identifies CDN and firewall restrictions, JavaScript challenges, CAPTCHAs, authentication, and geographic rules as potential access problems. These are useful places to investigate when the evidence points to a failed landing-page check. They are not reasons to disable protection across an entire website. [3]
A test request that copies a bot's user-agent text can reveal how your server responds to that text. It cannot reproduce the operator's network address, verification state, rendering behavior, or internal processing. Label the result as a response test and confirm actual subsequent activity separately.
Review recorded activity in Ansvra
When AI Agent Analyzer is available for your account and has request records for the website, use it to investigate the declared bot, requested pages, dates, and recorded response information. Ansvra recognizes OAI-SearchBot, GPTBot, ChatGPT-User, and OAI-AdsBot. Identity matching is separate from verifying that OpenAI operated the requester.
Start with the correct project and time period, then compare the relevant bots and requested pages. Review the source's coverage before interpreting an empty report. Uploaded history represents saved activity; it does not establish an ongoing connection. A missing observation should remain unknown rather than becoming evidence that the bot never visited.
Use the AI Agent Analyzer setup guide for current connection and access instructions. Review human visits separately in Traffic from AI, and inspect source links in saved AI answer evidence. These observations can inform the same investigation without proving a measured sequence between them.
Frequently asked questions
Can I allow ChatGPT search while blocking training collection?
Yes. OpenAI documents independent OAI-SearchBot and GPTBot preferences. Review the example above and merge the intended rules with your existing policy. Allowing search crawling still does not guarantee a search appearance. [1]
Does blocking GPTBot stop all ChatGPT visits?
No. GPTBot addresses training-related collection. Search discovery, certain user-requested visits, advertising checks, and signed browser traffic have separately documented roles. Choose the relevant control for the activity you are investigating. [1] [4]
Does a ChatGPT-User request mean my page appeared in search?
No. OpenAI says ChatGPT-User serves certain user actions and does not determine search inclusion. Inspect actual answer evidence for a citation and use OAI-SearchBot for the documented search opt-out. [1]
Why is OAI-AdsBot different from GPTBot?
It checks submitted ad pages for safety and potential relevance. OpenAI says the data it collects is not used for foundation-model training. Advertisers should follow its dedicated access checklist. [1] [3]
Should I use noindex, noai, or llms.txt as a universal OpenAI control?
Do not assume these mechanisms are interchangeable. The examples here implement OpenAI's documented bot-specific preferences. A page directive and a crawl restriction are different mechanisms, and an uncrawled page cannot reliably deliver a new directive through its body. Verify current operator support before relying on an additional mechanism. [1] [2]
How long should I wait after changing robots.txt?
OpenAI gives approximately 24 hours for its search systems to adjust. It does not describe that period as a guaranteed crawl or citation deadline, and the statement should not be generalized to every bot or request type. [1]
Can a robots rule protect confidential pages?
No. The Robots Exclusion Protocol is not access authorization. Use authentication and authorization for confidential information; keep public crawl preferences as a separate layer. [2]
Summary
Choose a policy for each purpose, review the exact bot and host, and verify the relevant request evidence before changing access. Search discovery, potential training collection, user-requested retrieval, and advertising checks need different interpretations. Once access is understood, review citations and human visits with their own evidence.
Discussion
Join the discussion