
Key takeaways
- A browser success does not establish that a crawler received the same response.
- Verify crawler identity using the provider’s documented methods; a user-agent string alone is not enough.
- Correlate edge events, origin records, and redirect hops before deciding where a 403 or 429 originated.
- A later 200 is useful evidence of access for that request, not a guarantee of indexing or citation.
An AI crawler can receive a 403 or 429 even when a page opens in your browser because the two requests may be handled differently. Start with the failed request—not the browser result: verify the crawler’s identity, trace its response through the edge and origin, and inspect any matching firewall or rate-limit event. Then make the narrowest appropriate change and check subsequent logs.
A 403 points you toward an access decision; a 429 points you toward request throttling. Neither code alone identifies which system made the decision. A reported crawler failure can also be intermittent, so compare the same URL and request conditions where possible. A community report describes an external crawler receiving a redirect followed by a 429, then receiving a 200 on a later single-URL check; it does not establish a common cause with Googlebot errors. [6]
1. Capture the failed request
Ask the team managing your CDN, firewall, or hosting platform for the relevant request records. Capture the timestamp and time zone, URL and query string, status code, user agent, source IP, request ID, and any redirect target. Record edge action or rule ID and origin response when available. Note fields that are missing rather than treating them as successful responses.
Compare the failed request with a browser request to the same URL. Differences in timing, source IP, user agent, redirects, and request volume are leads to investigate—not proof of the cause.
2. Verify who made the request
Do not grant access based on a user-agent string alone. For Google requests, Google documents either a reverse DNS lookup followed by a forward lookup that returns the original IP, or a match against its published crawler and fetcher IP ranges. Use the appropriate list for the type of request. [2]
For other providers, use their documented verification information. OpenAI publishes separate ranges for OAI-SearchBot and GPTBot; Perplexity recommends matching each bot’s user agent against that bot’s own published IP ranges. Check the current provider documentation and ranges before changing a rule. [3] [4]
Identify the purpose of the agent as well as its operator. OAI-SearchBot is used for search, while GPTBot crawls content that may be used for training. PerplexityBot is intended for search results; Perplexity-User supports user-initiated requests. Your access policy may differ for each. [3] [4]
3. Locate the decision: edge, origin, or redirect
- Edge: Look for a firewall or rate-limit event with the same request ID and timestamp. Record the action and rule that matched. A browser request may have taken a different path through those controls.
- Origin: Check whether there is a corresponding origin request and what it returned. If no origin record is available, that is not by itself proof that the edge blocked the request: logging or correlation may be incomplete.
- Redirect chain: Inspect each hop and its status rather than recording only the first response. In the community report above, the external crawler’s observed 429 followed a redirect; the report explicitly did not identify the request as verified Googlebot. [6]
For a 403, investigate the matching access or firewall decision first. For a 429, inspect the rate-limit event and the request activity around it, including any available counts and the scope of the limit. Escalate to the hosting provider if the available records point to a layer your team cannot inspect or control.
4. Check policy separately from enforcement
Review robots.txt for the specific crawler and your intended use. Allowing a crawler there is a policy choice; it is not the same check as determining whether a firewall permits its request. OpenAI documents independent settings for OAI-SearchBot and GPTBot and says search systems may take about 24 hours to adjust after a robots.txt update. [3]
If a verified crawler should have access and a firewall rule is responsible, ask the security owner to consider a targeted exception. For example, Perplexity’s documented Cloudflare approach combines each agent’s user-agent match with its own IP ranges, places a Skip rule before blocking rules, and specifies which security features to bypass. Its documentation also notes that Bot Fight Mode cannot be skipped with WAF custom rules. Verify current platform behavior before publication or implementation. [4]
For a confirmed rate-limit match, review the affected scope and threshold with the security owner before changing it. Avoid a broad bypass based only on a crawler name. Keep a record of the rule, owner, change time, and rollback approach.
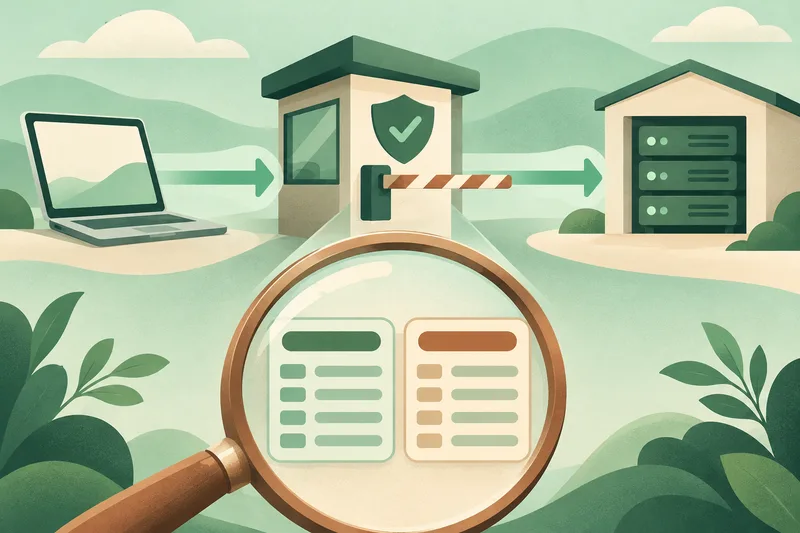
Before-and-after log check: an illustrative example
The following records and outcome are fictional. They show how to test a hypothesis; they are not evidence of a real incident or a guaranteed fix.
| Check | Before change | After change |
|---|---|---|
| Request | Same page, identified search crawler, 429 at the edge | Same page and verified crawler identity, 200 at the edge |
| Identity | Source IP matched the crawler’s published range at the time of review | Source IP checked against the current published range |
| Edge event | Rate-limit rule recorded as the matching action during a burst | The targeted exception matched; no rate-limit action recorded for this request |
| Origin | No corresponding origin record found; reason unconfirmed | Matching origin record returned 200 with the expected page content |
In this scenario, the team checked the verified identity and matching edge event, then adjusted only the relevant rule for the intended crawler. The later edge and origin records support the conclusion that this particular request got through. Continue monitoring comparable requests: one 200 does not prove that every future crawl will succeed or that the page will be indexed.
Also inspect the response content, not just the status. Google says a 200 response is passed to its next processing step, but indexing is not guaranteed; it can also identify an error page returned with a success status as a soft 404. [1]
Use recorded activity without overinterpreting it
Ansvra’s AI Agent Analyzer is intended to help teams review recorded crawler activity, the pages requested, and responses needing attention. Use it to find a time and URL to investigate, then corroborate the decision in the available edge and origin records. A crawler request is not proof that an AI answer cited the page. Confirm current product and connection details before publication.
Next steps for the affected crawler request
- Save the failed URL, timestamp, source IP, user agent, status, and available request ID.
- Verify the IP using the crawler provider’s current documentation and identify the agent’s purpose.
- Correlate the request with edge rules, origin logs, and any redirect chain.
- Have the security owner review a narrowly scoped change if a rule is confirmed as the cause.
- Compare subsequent verified requests and expected response content with the pre-change records.
FAQs
Does a page working in my browser mean an AI crawler can access it?
No. A reported case describes normal browser access alongside an external crawler’s intermittent redirect and 429; a later single-URL crawler check returned 200. That report does not establish the underlying cause. [6]
Can I verify a crawler from its user-agent string?
Do not rely on the string alone. Google documents DNS verification or matching against published IP ranges. Perplexity recommends combining each bot’s user-agent match with its own published IP ranges. [2] [4]
Does allowing OAI-SearchBot also allow GPTBot?
No. OpenAI says their robots.txt settings are independent: OAI-SearchBot is used for search, while GPTBot crawls content that may be used for model training. [3]
Does a 200 response guarantee indexing?
No. Google says it passes a 200 response to the next processing step, but indexing is not guaranteed. It may also report a soft 404 when a success response contains an error page. [1]
Sources
- How HTTP Status Codes Affect Google's Crawlers | Google Crawling Infrastructure | Crawling infrastructure | Google for Developers - How HTTP status codes affect Google's crawlersStay organized with collections Save and categorize content based on youAccessed
- Verify Requests from Google Crawlers and Fetchers | Google Crawling Infrastructure | Crawling infrastructure | Google for Developers - Verify requests from Google crawlers and fetchersStay organized with collections Save and categorize content basedAccessed
- Overview of OpenAI CrawlersAccessed
- Perplexity Crawlers - PerplexityAccessed
- Why are Blogger sites returning HTTP 429 / Google “Sorry” pages to crawlers?Accessed
- Blogger live test passes but Googlebot has redirect errors and external crawler gets HTTP 429 - Send feedback onAccessed
Discussion
Join the discussion