
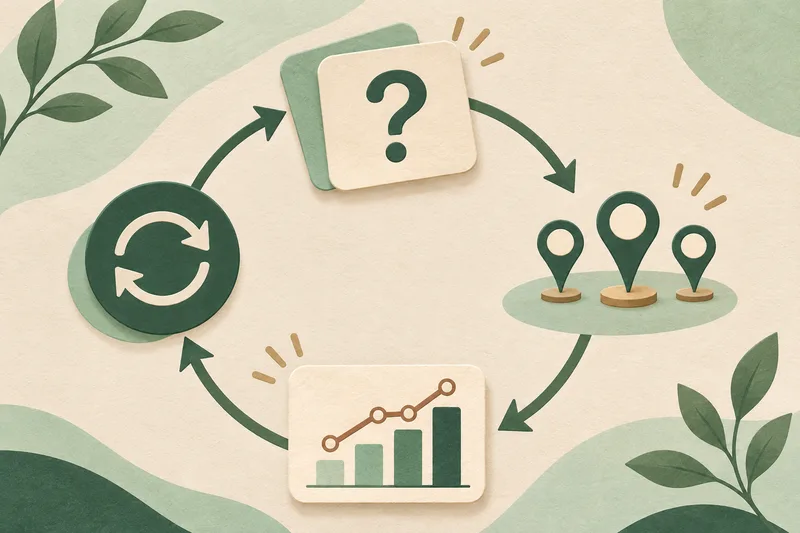
Build an AI visibility benchmark by running the same set of customer questions on the same platforms and in the same market, then recording whether each valid answer mentions your brand or cites your website. Keep missing responses visible rather than counting them as negative results.
Start with the 20-question matrix below. It is an illustrative template, not a set of verified customer queries. Adapt the placeholders to your business, review the wording with your team, and freeze the final list before your first run.
1. Define the benchmark before you run it
Write down the scope so someone else can repeat the test:
- Brand and website: List the brand names and aliases that count as a mention, plus the website domains that count as a citation.
- Platforms and surfaces: Name each product and, where relevant, the specific experience being tested. Verify current platform names and availability before publication or reporting.
- Market: Record the country, language, and any location settings used.
- Prompt version: Save the exact wording and ID of every question. Define placeholder values consistently across the matrix.
- Run procedure: Set the number of attempts per prompt, platform, and market; the schedule; and whether each attempt starts in a fresh conversation. Record relevant account, device, and search settings.
Keep surfaces separate in the results. For example, Google says AI Overviews and AI Mode may use different models and techniques and show different responses and links. An AI Overview also may not appear for every query. Source: Google Search Central
2. Use this 20-question starter matrix
Replace bracketed terms with your own customer problem, category, use case, brand, and named competitors. Choose competitors before the first run rather than changing them between runs. These prompts are starting points; edit them to reflect the questions your audience actually asks.
| ID | Intent | Starter question |
|---|---|---|
| P1 | Problem | How can I solve [customer problem]? |
| P2 | Problem | What causes [customer problem], and how can I address it? |
| P3 | Problem | What should a [team type] do first when dealing with [customer problem]? |
| P4 | Problem | What are common approaches to [customer problem] for [use case]? |
| P5 | Problem | What should I consider before choosing a solution for [customer problem]? |
| C1 | Category | What is [product category], and who is it for? |
| C2 | Category | What should I look for in a [product category] for [use case]? |
| C3 | Category | Which [product category] options should a [team type] consider? |
| C4 | Category | How do I evaluate [product category] options for [customer problem]? |
| C5 | Category | What questions should I ask before adopting a [product category]? |
| V1 | Comparison | How do [brand] and [competitor A] compare for [use case]? |
| V2 | Comparison | What are the alternatives to [competitor A] for [use case]? |
| V3 | Comparison | How do [competitor A] and [competitor B] differ for a [team type]? |
| V4 | Comparison | Which factors matter when comparing [brand] with [competitor A]? |
| V5 | Comparison | What alternatives to [brand] should I evaluate for [customer problem]? |
| B1 | Brand | What does [brand] do? |
| B2 | Brand | Who is [brand] intended for? |
| B3 | Brand | How does [brand] approach [customer problem]? |
| B4 | Brand | What should I know before considering [brand] for [use case]? |
| B5 | Brand | Where can I find information about [brand] and [product category]? |
Report the four intent groups separately as well as together. Brand and some comparison questions explicitly name your brand, so their mention rates should not be interpreted like those for unbranded problem or category questions.
3. Log every attempt, including missing responses
Create one row per prompt, platform, market, and attempt. Store the answer or a link to your saved evidence when available.
| Field | What to record |
|---|---|
| Run and prompt | Run ID, prompt ID, exact wording, intent group, and prompt version |
| Conditions | Platform and surface, market, language, run date and time, and relevant account or device settings |
| Attempt and status | Attempt number and status: valid answer, feature not shown, error, or other missing response |
| Brand mention | Yes or no for a valid answer, using the aliases defined in advance |
| Website citation | Yes or no for a valid answer, using the domains defined in advance; record cited URLs when present |
| Evidence and notes | Saved answer or evidence reference, missing-response reason, and any relevant context or accuracy concern |
Decide in advance how to handle refusals or partial answers. Record them consistently; do not silently convert them into brand absences. If you retry an error, retain the original attempt and label the retry so the coverage record stays intact.
4. Calculate coverage, mentions, and citations separately
- Coverage: Valid answers ÷ planned attempts. Report the count of missing responses and their reasons alongside it.
- Brand mention rate: Valid answers that mention the brand ÷ valid answers.
- Website citation rate: Valid answers that cite an approved website domain ÷ valid answers.
Show the numerator and denominator for each rate. If there are no valid answers in a group, report the rate as unavailable—not zero. A brand mention and a website citation are distinct observations, so do not combine them into one score without explaining the rule.
Review rates by platform, market, and intent before looking at the overall figure. If the number of missing responses changes substantially between runs, investigate coverage before interpreting a rate change.
5. Repeat the run and turn findings into work
- Rerun the frozen matrix. Use the same wording, placeholder values, platforms, markets, settings, and attempt count. Note any unavoidable changes.
- Compare like with like. Check the valid-answer counts and missing-response reasons for each group before comparing rates.
- Inspect the evidence. Review answers for incorrect descriptions, uncited mentions, cited pages, and questions where your brand is absent. Treat each as a lead for investigation, not proof of a cause.
- Prioritize a response. Assign an owner and a relevant page or content gap. For Google Search, check foundational requirements such as indexing, snippet eligibility, crawl access, internal links, and helpful content. Source: Google Search Central
- Record changes and measure again. Keep a dated change log, then compare the next run against the same baseline. A change in a benchmark alone does not establish that a particular edit caused it.
Use platform reporting as a complementary view, not a substitute for the prompt log. Google says AI feature appearances are included in overall Search Console Web search reporting. Bing describes its AI Performance public preview as reporting citation activity across supported AI experiences; its citation counts do not indicate placement within a specific answer. Verify current availability and definitions before relying on either report. Source: Google Search Central; Source: Bing Webmaster Tools
When should you change the matrix?
Keep a stable core for trend comparisons. If a prompt no longer fits the business, retire or revise it with a new version and date. Report the old and new versions separately rather than treating them as the same question. Add new prompts as a clearly labeled expansion, and establish their own baseline.
Discussion
Join the discussion